
VRAMStack — Local LLM GPU VRAM, inference speed & API cost calculator
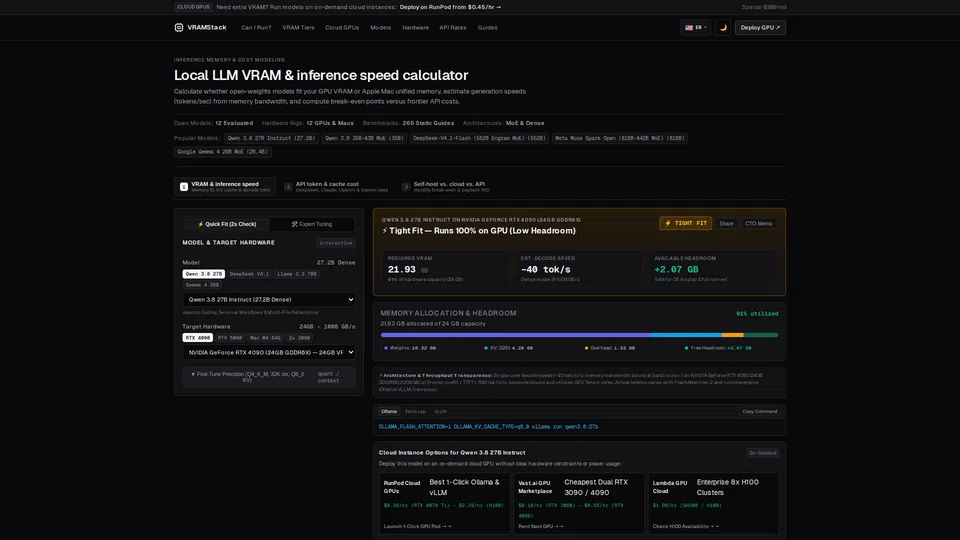
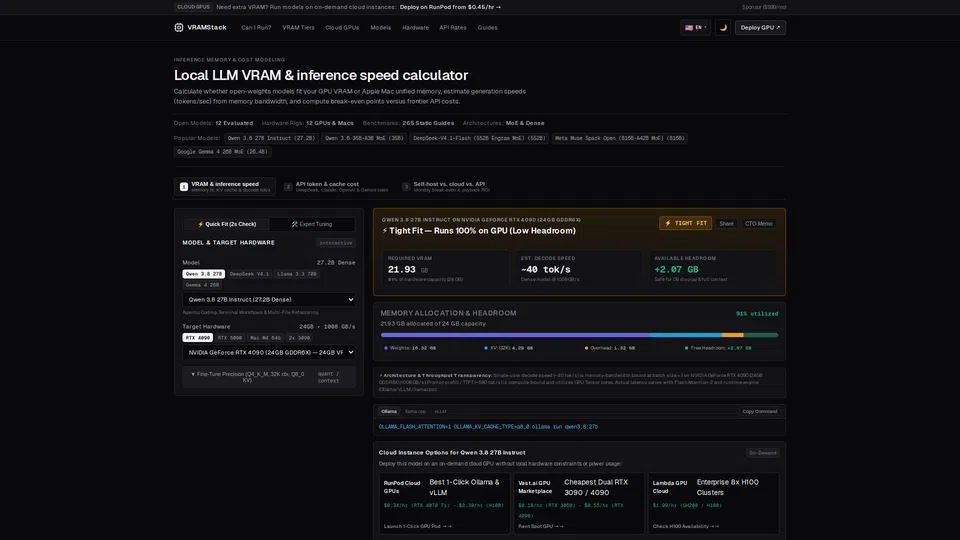
VRAMStack is a technology-focused platform that provides a local LLM VRAM and inference speed calculator to help developers assess memory usage, performance, and cost when running language models on local hardware or cloud GPUs. The site offers interactive models, hardware comparisons, and guidance for optimizing model deployments, appealing to AI practitioners, researchers, and developers evaluating options for efficient inference and budgeting.
We analyze text and images across millions of websites using similarity detection to identify large-scale content duplication and reuse.
This signal indicates whether widespread duplication patterns were detected at the time of analysis.
Signals update over time.

Discussion
Log in to comment or vote.